The combination of the two is suitable for organizations operating with different subgroups that require a customized technique to the data collection method. Fetch top quality data from any kind of target without IP obstructs and CAPTCHA. Rotating proxies change per request or within particular intervals, minimizing the possibilities of obtaining obstructed by an internet site's safety and security. Have a look at exactly how the two procedures vary particularly facets to gain even more insight. It gathers data by recording the individual's display-- typically with the user's consent. We're a location where coders share, remain up-to-date and grow their occupations.
This information might additionally consist of metadata for category objectives. Financial services usually utilize this to collect and evaluate customer data. Is extra typical today than manual "copy/paste." Nonetheless, by hand gathering information from web pages can still benefit smaller sized tasks. Nevertheless, they typically overlap-- so it's easy to swap these terms. We set up, release and preserve work in our cloud to remove information with best. Calls for a space to be saved on, bringing some expenses to the individuals.
Google faces lawsuit over copyright infringement, data scraping for AI expansion Mint - Mint
Google faces lawsuit over copyright infringement, data scraping for AI expansion Mint.
Posted: Wed, 12 Jul 2023 07:00:00 GMT [source]
Modern creeping bots are developed to better recognize what the limits of procedures are and abide within the constraints to avoid lawful complications. As a result of these technological innovations, the danger of upseting are very little. Web scraping is everything about the data - the information fields you want to draw out from particular internet sites. With scuffing you usually know the target web sites, you may not understand the details web page Links, yet you recognize the domains a minimum of.
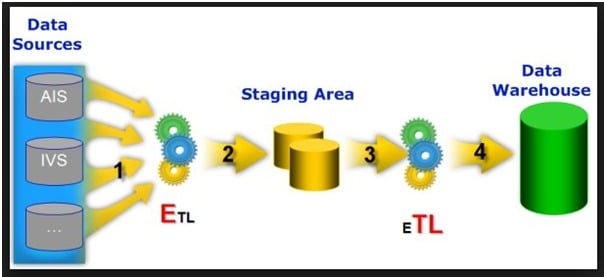
Data Scratching For Service
In this manner, it does not always need to be pulled from the internet alone, as it can in fact be drawn from any place where data Click for source exists. This does not pull specifically from the internet, it can be taken from anywhere that data exist. This can include spread sheets, storage tools, etc, anywhere information exist Custom Business Intelligence Services in any kind of type.
Google's big AI push will combine Brain and DeepMind into one team - The Verge
Google's big AI push will combine Brain and DeepMind into one team.
Posted: Thu, 20 Apr 2023 07:00:00 GMT [source]
It's possible to scrape PDFs, pictures, and other offline papers also. The vital difference between internet scratching and data scraping is that internet scuffing occurs exclusively on the internet. It's like a subset of data scratching, which can happen online or offline.
Web Crawling Vs Internet Scraping
We can select either strategy depending on the nature of information we are looking up. Information scratching and information crawling can be based on a range of difficulties, such as legal and moral issues, technical troubles, and high quality concerns. It is very important to value the information owner's civil liberties and approvals, and stay clear of any kind of offenses of the legislation. Some web pages or papers might have dynamic, complicated, or encrypted web content that can make data scratching or creeping challenging or impossible. To conquer these obstacles, you might need to utilize innovative techniques, such as web browser automation, proxies, or APIs. Furthermore, some pages or papers might have imprecise, insufficient, or obsolete data that can influence the reliability and validity of your results.
- You aren't necessarily locating brand-new material by doing a crawl on your own computer system.
- The objective of crawling is often to develop an index or catalog of data, which can then be searched or assessed.
- Information scratching, on the other hand, refers to the removal of data from any type of source.
- After that for each and every new item, a scraper is utilized to draw out the new product's information, like the price, pictures, item code, or description.
- We have actually assisted remove internet data for more than 1,000 clients ranging from Federal government Agencies and Fortune 100 companies to early-stage start-ups and people.
Limitation your information scraping or creeping regularity and speed to avoid overloading or crashing the internet servers. Examination and debug your code before running it on the real websites or records, handling any type of mistakes or exemptions that might happen during the information removal procedure. Shop and manage your information in a protected and well organized way with proper styles, such as CSV, JSON, or SQL. Also keep in mind to backup your information on a regular basis and delete or archive any kind of obsolete or unnecessary information. Information crawling obtained Custom business intelligence solutions its name from spiders that creep around the properties. A digital "crawler" can crawl around the Internet, indexing pages of various internet sites.
During this time around we gained a remarkable quantity of experience and knowledge in internet data removal. For organizations, it makes good sense to not stress over crawling and scuffing so you can concentrate purely on the understandings from that data. Internet information companions like Zyte can care for all the inconveniences of internet scraping.
A lot of the use cases for internet scratching remain in an organization context. A company could wish to inspect what products its competitors are marketing and the costs they are offering them at. They may likewise wish to check sites for any points out of them or to find information that will help with their search engine optimization technique.